V 2.0 The New (Old) Genetics
Abstract
The field of Genetics started flourishing after the re-discovery of the Mendelian laws of inheritance at the beginning of the 20th century. These laws are based on a discrete classification of phenotypes and their causative genes. Such a Mendelian way of thinking forms the foundation of modern molecular biology, with its experimental paradigm that a gene function is inferred from the knock-out of the gene. However, most phenotypes are not discrete. Human height, for example, is a continuous phenotype and height measures approximate a Gaussian distribution. The statistical foundation for the genetics of human height was worked out by Galton at the end of the 19th century. He established the basis of quantitative genetics, a field that has driven the agricultural and breeding programs in the past century. With the beginning of the 21st century, the technical developmnts behind the human genome project have paved the way to reconcile the two contrasting ways of genetic thinking – Mendelian genetics and statistical genetics – through genome-wide analyses. It has now become clear that most phenotypes are rarely determined by single Mendelian genes, but instead, many genes contribute to polygenic determination and variation. It has even been suggested in the omnigenic model that all genes that are expressed at the appropriate time contribute to any given phenotype. These insights are stimulating a major re-thinking of how the linear genetic information laid down in the deoxyribonucleic acid (DNA) is converted into the three-dimensional structure of an individual. The new conceptual and experimental paradigms have already revolutionized animal and plant breeding. In the field of human genetics, the realization that common diseases have a polygenic basis is raising new challenges for treatment. And finally, in basic sciences like molecular and evolutionary biology, researchers are starting to revisit traditional, but oversimplified concepts on how genes act and how evolutionary adaptation works.
General Lay Summary
When one thinks of genetics, the first thing that comes to mind is Mendel. Mendelʼs laws are taught at an early age in school and for many school leavers they remain the only contact with genetics. Yellow and green peas are used to show how traits are inherited, how mixing and splitting can occur. However, while such categorial thinking has fueled the development of modern molecular genetics, it does not reflect the fact that neither the common phenotypes, nor their inheritance, can be described in these terms. Instead, the rules of quantitative genetics apply to most visible manifestations of organisms. The principles of quantitative genetics have been worked out by a contemporary of Mendel – Francis Galton. However, they have led for a long time a shadow existence, only familiar to animal and plant breeders. Among quantitative geneticists, statistics prevail. There are no categorical distinctions, such as the green and yellow peas, but only continuous distributions, such as body size.
With the tools of genomics, it is now possible to determine for each individual gene in the genome what proportion it makes up of a continuous phenotype, for example the body size. One can then ask how much of the total height is due to each of the genetic variants. To obtain such data, several hundred thousand individuals with millions of variants had to be screened. The results showed that height is determined by the variants of very many genes with very small effects each. Some geneticists now even assume that ultimately all genes in a genome contribute to each phenotype in varying proportions, the so-called “omnigenic model”.
While quantitative genetics teaches that there are no genetic categories, our thinking is still mainly shaped by categories. For example, it is easy for us to understand how the categories “male” and “female” are determined by the distribution of the X and Y chromosomes according to Mendel’s rules. However, it seems more complicated to recognize that quantitative genetics principles apply to many other characteristics that we associate with male and female categories, like physical attributes, sexual preferences, and sexual behavior. And therefore, instead of a clearcut separation of male and female, nature presents us with continuous and overlapping distributions of physical and behavioral characteristics. If our schools had always taught quantitative genetics, many misunderstandings of genetics and inheritance would have been prevented.
Generelle Zusammenfassung
Wenn man an Genetik denkt, kommt einem als Erstes Mendel in den Sinn. Mendels Gesetze werden schon früh in der Schule gelehrt, und für viele Schulabgänger bleiben sie der einzige Kontakt mit der Genetik. Gelbe und grüne Erbsen werden verwendet, um zu zeigen, wie Merkmale vererbt werden, wie Vermischung und Aufspaltung einzelner Merkmale auftreten können. Doch ob-wohl ein solches kategoriales Denken die Entwicklung der modernen Molekulargenetik beflügelt hat, spiegelt es nicht die Tatsache wider, dass weder die Körperformen und Verhaltensformen, noch deren Vererbung mit diesen Begriffen beschrieben werden kön-nen. Stattdessen gelten für die meisten sichtbaren und messbaren Ausprägungen von Organismen die Regeln der quantitativen Genetik. Die Prinzipien der quantitativen Genetik wurden von einem Zeitgenossen von Mendel – Francis Galton – ausgearbeitet. Sie haben jedoch lange Zeit ein Schattendasein geführt und waren meist nur Tier- und Pflanzenzüchtern bekannt. In der quanti-tativen Genetik herrscht die Statistik vor. Es gibt keine kategorialen Unterscheidungen, wie grüne und gelbe Erbsen, sondern nur kontinuierliche Verteilungen, wie z. B. die Körpergröße.
Mit den Werkzeugen der Genomik ist es nun möglich, für jedes einzelne Gen im Genom zu bestimmen, welchen Anteil es an einem kontinuierlichen Merkmal hat, z. B. der Körpergröße. Man kann dann fragen, wie viel von der Gesamtgröße auf jede der genetischen Varianten zurückzuführen ist. Um solche Daten zu erhalten, mussten mehrere hunderttausend Individuen mit Millionen von Varianten durchmustert werden. Die Ergebnisse zeigten, dass die Körpergröße durch die Varianten sehr vieler Gene mit jeweils sehr geringen Auswirkungen bestimmt wird. Einige Genetiker gehen inzwischen sogar davon aus, dass letztlich alle Gene in einem Genom zu jedem Phänotyp in unterschiedlichen Anteilen beitragen, das sogenannte „omnigene Modell“.
Obwohl die quantitative Genetik lehrt, dass es keine genetischen Kategorien gibt, ist unser Denken immer noch hauptsächlich von Kategorien geprägt. So ist es für uns leicht nachvollziehbar, dass die Kategorien „männlich“ und „weiblich“ durch die Verteilung der X- und Y-Chromosomen nach den Mendelschen Regeln bestimmt sind. Es scheint jedoch komplizierter zu sein, zu erkennen, dass die Prinzipien der quantitativen Genetik auch für viele andere Merkmale gelten, die wir mit männlichen und weiblichen Kategorien in Verbindung bringen, wie z. B. körperliche Eigenschaften, sexuelle Vorlieben und sexuelles Verhalten. Anstelle einer klaren Trennung von männlich und weiblich finden wir in der Natur also eine kontinuierliche und sich überschneidende Verteilung von Körperformen und Verhaltensformen. Wenn in unseren Schulen immer quantitative Genetik gelehrt worden wäre, hätten viele Missverständnisse über Genetik und Vererbung vermieden werden können.
Keywords
Background
The foundations of modern genetics were independently laid down in the second half of the 19th century by Gregor Mendel (Mendel 1866) and Francis Galton (Galton 1889). But they came to different major conclusions. While Mendel emphasized the independent combination of discrete characters, such as green versus yellow peas, Galton focused on the statistical principles that describe continuous phenotypes, such as human height. This is not to say that Mendel was not aware that the characters he chose were not as discrete as he would have wished. But “seeing” of simple patterns at the expense of complexity was one of his major achievements, largely as a perceived necessary strategy to penetrate the complexity (Nasmyth 2022, Weeden 2016). Up until today this distinction of discrete versus continuous characters endures in reflecting the fundamental dichotomy in looking at mechanisms of inheritance. In fact, it is rather comparable to the particle-wave duality of quantum mechanics. Einsteinʼs quote on this duality could almost seamlessly be applied when exchanging the term “light” with “genetics”:
“It seems as though we must use sometimes the one theory and sometimes the other, while at times we may use either. We are faced with a new kind of difficulty. We have two contradictory pictures of reality; separately neither of them fully explains the phenomena of light, but together they do.” (Einstein and Infeld 1938)
In biology a basic theory for resolving this duality was worked out in the early 20th century, most systematically by Ronald Fisher. He formulated what is nowadays called the infinitesimal model of inheritance:
“The simplest hypothesis […] is that such features as stature are determined by a large number of Mendelian factors, and that the large variance among children of the same parents is due to the segregation of those factors in respect to which the parents are heterozygous.” (Fisher 1918)
However, experimental proof of Fisherʼs postulated “large number of Mendelian factors” was lacking for a long time and is only now beginning to emerge. Hence, Mendelian genetics – understood as one gene, one discrete phenotype – has prevailed in textbooks and public understanding. This is even embodied in conventions of gene naming, where genes are often named according to their mutant phenotype. Since discrete phenotypes can be measured accurately, the experimental results are more straightforward and easier to communicate. This results in a perceived value in suggesting a simple mechanistic understanding of phenotypic variation. Even in physics we still prefer mechanical over quantum laws, although both are required to explain the real world.
Mendel’s genetics has laid down the foundations for molecular genetics and is still dictating its experimental paradigms. Galton’s genetics, on the other hand, laid down the foundations of quantitative genetics, correlative statistics and biometry (further worked out by Karl Pearson and Raphael Weldon, who teamed up with Galton in the early 1900s). This then became the basis for the progress in agricultural plant and animal breeding in the 20th century. A reunion of these rather separate developments – molecular and quantitative genetics – has only started with the genomic revolution in the 21st century, especially with the developments in genome-wide association studies (GWAS) that allow the simultaneous interrogation of all genes in the genome for their effect on a given phenotype. This is already revolutionizing breeding experiments and the understanding of complex diseases. We are still only in the beginning of these developments, where new concepts and insights are being turned out at a high rate. We are entering a phase where the long-standing unresolved question of the relationship between the genotype and the phenotype is receiving new impulses and fresh experimental paradigms are starting to emerge. This will have major impacts on further disciplines. In evolutionary biology it will help to understand the mechanisms of genetic adaptation. In developmental biology it will help to understand how the linear information from the DNA gets converted into the three-dimensional Gestalt of an individual. In medicine it will allow us to understand the basis of complex diseases, including a re-thinking of strategies for developing new pharmaceuticals. And we will finally have a better understanding of the role of the environment versus genetic determinism in the formation of the Individuum, including its self-identification in the female-male spectrum.
Galton’s Legacy
“[...] to show the large part that is always played by chance in the course of hereditary transmission, and to establish the importance of an intelligent use of the laws of chance [...] in expressing the conditions under which heredity acts.” (Galton 1889, p. 17.)
Galton was interested in understanding the mechanisms of heredity throughout his scientific life. While focusing a lot on inheritance patterns in humans, he also did breeding experiments with sweat-peas and moths. Especially with the latter, he could also have discovered Mendel’s rules, but his focus was on continuous phenotypes, rather than discrete ones. He realized that continuous phenotypes can only be described with a statistical treatment of the group of relatives from the preceding generations, while Mendel had focused on describing phenotypic categories without including a statistical treatment. The statistical techniques and principles that Galton developed and discovered include correlation, the importance of the median, the concept of standard deviations, the regression to the mean, the use of questionnaires, and, based on twin studies, the role of the environment for expressing the phenotype.
Galtonʼs most important book on the principles of heredity is Natural Inheritance (Galton 1889). It is an extremely scholarly book, solidly based on data and innovative ways of analysis (and eugenics plays no role in it). It remains very readable, being full of explanations and thoughts that led to his conclusions and largely remain valid until today. It would be fair to say that in its implications it should be considered as being comparable with his half-cousins’ book on the Origin of Species (Darwin 1859) and it would deserve to be equally hailed. But it was apparently received with much more skepticism (Stanley 1889).
One of Galtonʼs great ideas to obtain data for statistical analysis was the public offering of prizes for sending him personal data. He published an advertisement in newspapers starting with “Mr. Francis Galton offers 500£ in prizes to those British Subjects resident in the United Kingdom who shall furnish him before: May 15, 1884, with the best Extracts from their own Family Records.” (Galton 1889), followed with detailed descriptions of what he wanted. And, not much different from today, people were very willing to provide their personal data when a reward is promised (e.g., use of a “free” internet service). Galton was at that time mostly interested in the inheritance of human height, since this is a continuous trait that can be objectively measured. He received useable datasets from 150 extended families and given that these families were much larger in these times, these data remain valuable until today.
Galton used these data (together with other data from eye color, as well as his experiments on peas and moths) to work out key principles of quantitative genetics. He showed that the height measurements had a statistically normal – or Gaussian – distribution (a hallmark of all quantitative phenotype data), that there was a sex-specific effect that he could correct with a single factor and that the midpoint average between the mother’s and the father’s height correlated linearly with the height of the offspring. But he noted also that the offspring of tall parents tended to be somewhat smaller than expected from a pure linear correlation and the offspring from short parents tended to be somewhat larger. He called this effect “regression to mediocrity” (nowadays: regression to the mean) and it is by now well understood that this is a general effect of statistical sampling (Barnett, van der Pols and Dobson 2005). To Galton this suggested that many independent “particles” must be involved in height determination and that these were passed on over the generations. One of his key conclusions was therefore:
“We appear, then, to be severally built up out of a host of minute particles of whose nature we know nothing, anyone of which may be derived from any one progenitor, but which are usually transmitted in aggregates, considerable groups being derived from the same progenitor.” (Galton 1889)
He provides there an almost modern description of a polygenic inheritance with chromosomal linkage. Although Galtonʼs work on heredity was ground breaking and has led to many further developments in statistics and animal and plant breeding, its true value for understanding core principles of genetics has been largely overlooked for more than a century. Intriguingly, the imminent resurrection of these principles in the genomics age has come again from human height studies. Extensive GWA studies revealed that the principles of Mendelian genetics that have dominated the last century of genetics research need to be complemented by statistical genetics. Gene functions have both a particulate, as well as a statistical nature and both need to be considered for a full understanding of genetic architectures and their products, the living organism.
The Role of the Environment in Shaping the Phenotype
Quantitative trait phenotypes are not only determined by genes, but also the environment in which they develop. This is most obvious for plants where genetically identical individuals can be generated through cuttings and then planted in different soils or at different geographic elevations (Bradshaw 1965). Such experiments have shown that genotype alone is not sufficient to predict the phenotype in different environments, where they can grow to different heights or even display different phenotypes. Such results suggest that the environment modulates genetic effects that regulate phenotypic variation. The actual phenotype of an individual is therefore always considered to reflect a combination of genotype (G) and environmental effects (E) – and this is known as genotype-by-environment interactions (GxE). This applies also to animals: in two classic studies in Drosophila, it was shown that bristle numbers (Gupta and Lewontin 1982) and wings’ cross veins could change depending on temperature (Waddington 1953). And, such changes in response to environmental conditions had a genetic basis suggesting genotype-by-temperature interactions. More recently, advances in high-throughput sequencing that allow for the collection of large samples of genetically-variable individuals in environmentally controlled conditions, have allowed not only the quantification of GxE interactions, but even the identification of the genomic loci and genes that exhibit such behaviors (Pallares et al. 2023). GxE interactions are of particular relevance in plant breeding, where new varieties need to be tested in a range of environmental conditions to ensure maximal productivity. In humans, the environmental effect on human phenotypes is often discussed in terms of nurture (environment) versus nature (genetics), but it is now accepted that both factors don’t act in isolation, but do indeed interact to determine, for example disease etiology (Liu et al. 2012). The environment plays also a role in the development of human cognitive abilities, often measured via an IQ test. GWA studies have shown that cognitive abilities have a highly polygenic basis and depend on the socioeconomic conditions in which individuals grow up (Deary, Cox and Hill 2022, Rask-Andersen et al. 2021).
Continuous versus Discrete Thinking Regarding Human Traits
One of the hallmarks of continuous phenotypes is that their measurement values can often be approximated by a Gaussian distribution (sometimes informally also called a bell curve, Hernstein and Murray 1994). Gauss had derived this distribution from error theory to identify the real value from a set of measurements with errors. As discussed above, this made Galton believe, right from the beginning, that, to explain this observation, there must be a statistical sampling effect among many “particles” derived from progenitors. But initially, this turned out to be in contrast to Mendelʼs laws when they were rediscovered at the beginning of the 20th century. These laws state that discrete genotype classes are formed through the combination of alleles of a single gene. This should usually result in discrete phenotype categories, rather than a continuous Gaussian distribution (see (Berry and Browne 2022) for a discussion of the history around the rediscovery of Mendel’s laws).
In fact, this is the fundamental clash between what is taught in school about Mendelian genetics and what the real-life experience of inheritance is. The phenotype categories that lead to the Mendelian rules are very useful abstract concepts, but the actual phenotypes that one encounters in everyday life almost never fall into simple categories. This led to many misunderstandings, especially with respect to the common thinking that “a gene” would determine a given trait. But in genetics, there are practically no cases of such simple scenarios for non-disease-associated phenotypes.
The typical school examples for teaching Mendelian rules include eye color determination in humans. It is still often portrayed as being determined by a single gene with two alleles, whereby brown eyes are said to be dominant to blue eyes. Under this model, parents with blue eyes could not have a child with brown eyes. Although this is indeed uncommon, parents with blue eyes can have children with brown eyes since there are at least 16 genes responsible for eye color, with complex interactions among them that can produce different color outcomes (White and Rabago-Smith 2011).
The other main school example is the genetics of sex determination through sex chromosomes. This is indeed nominally very simple, since the combinations of the sex chromosomes X and Y yield (at least in most mammals) a female in the XX combination and a male in the XY combination, i.e., two categories (Fig. 1A). But “male” and “female” are not distinct categories at the level of their adult phenotypes. Just the opposite, secondary sexually determined characters, such as the average height, are variable between individuals and when they are quantitatively measured, they fall into continuous, but overlapping Gaussian distributions (Fig. 1B).
The genetics of sexual orientation was also directly studied by GWAS and it was found to be highly polygenic, i.e., there is no single allele that has a major influence on this behavior (Ganna et al. 2019). The corresponding behavioral phenotypes are therefore bound to overlap, similar as height. The suggestion of sex differences in the brain has also drawn much attention, starting from physiological and morphological observations to developmental and hormone regulation considerations (Maney 2016). Given that each of these characters is most likely itself polygenically determined, it is not surprising that the relationships must be complex (Joel, Garcia-Falgueras and Swaab 2020). In a systematic analysis of whether gender differences are categorical or dimensional. (Reis and Carothers 2014, p. 19) concluded that
“[...] for the psychological constructs that we examined, there is little support for believing that sex differences are anything more than individual differences that vary in magnitude from one attribute to another.”
Behavioral and physical characteristics associated with gender identity are evolutionarily determined developmental processes that should not be put into binary categories (Box 2).
A particularly problematic form of discrete thinking has emerged in the discussion around the inheritance of intelligence. The measurement of “intelligence” via intelligence quotient (IQ) tests yields continuous values and any discussion of its heredity should therefore be fully in the realms of Galton’s genetics. But some authors have assigned average IQ values to subpopulations and implicitly treat these as discrete characters for these populations. When this is combined with claims of differences in average fertility for these population groups, they end up with scenarios of predicted substitutions of populations. But such discrete thinking is alien to quantitative genetics and this line of arguments is therefore wrong on many accounts. First of all, even if only parents from one end of the distribution would have children, one would still recreate almost the same variance in IQ distribution as before (see Box1, part B). Only the population average could slightly change, and even this would not happen as long as there is at least some population mixing. Hence, it would dramatically help in such a discussion if the principles of quantitative genetics would be taught in school alongside the principles of Mendelian genetics.
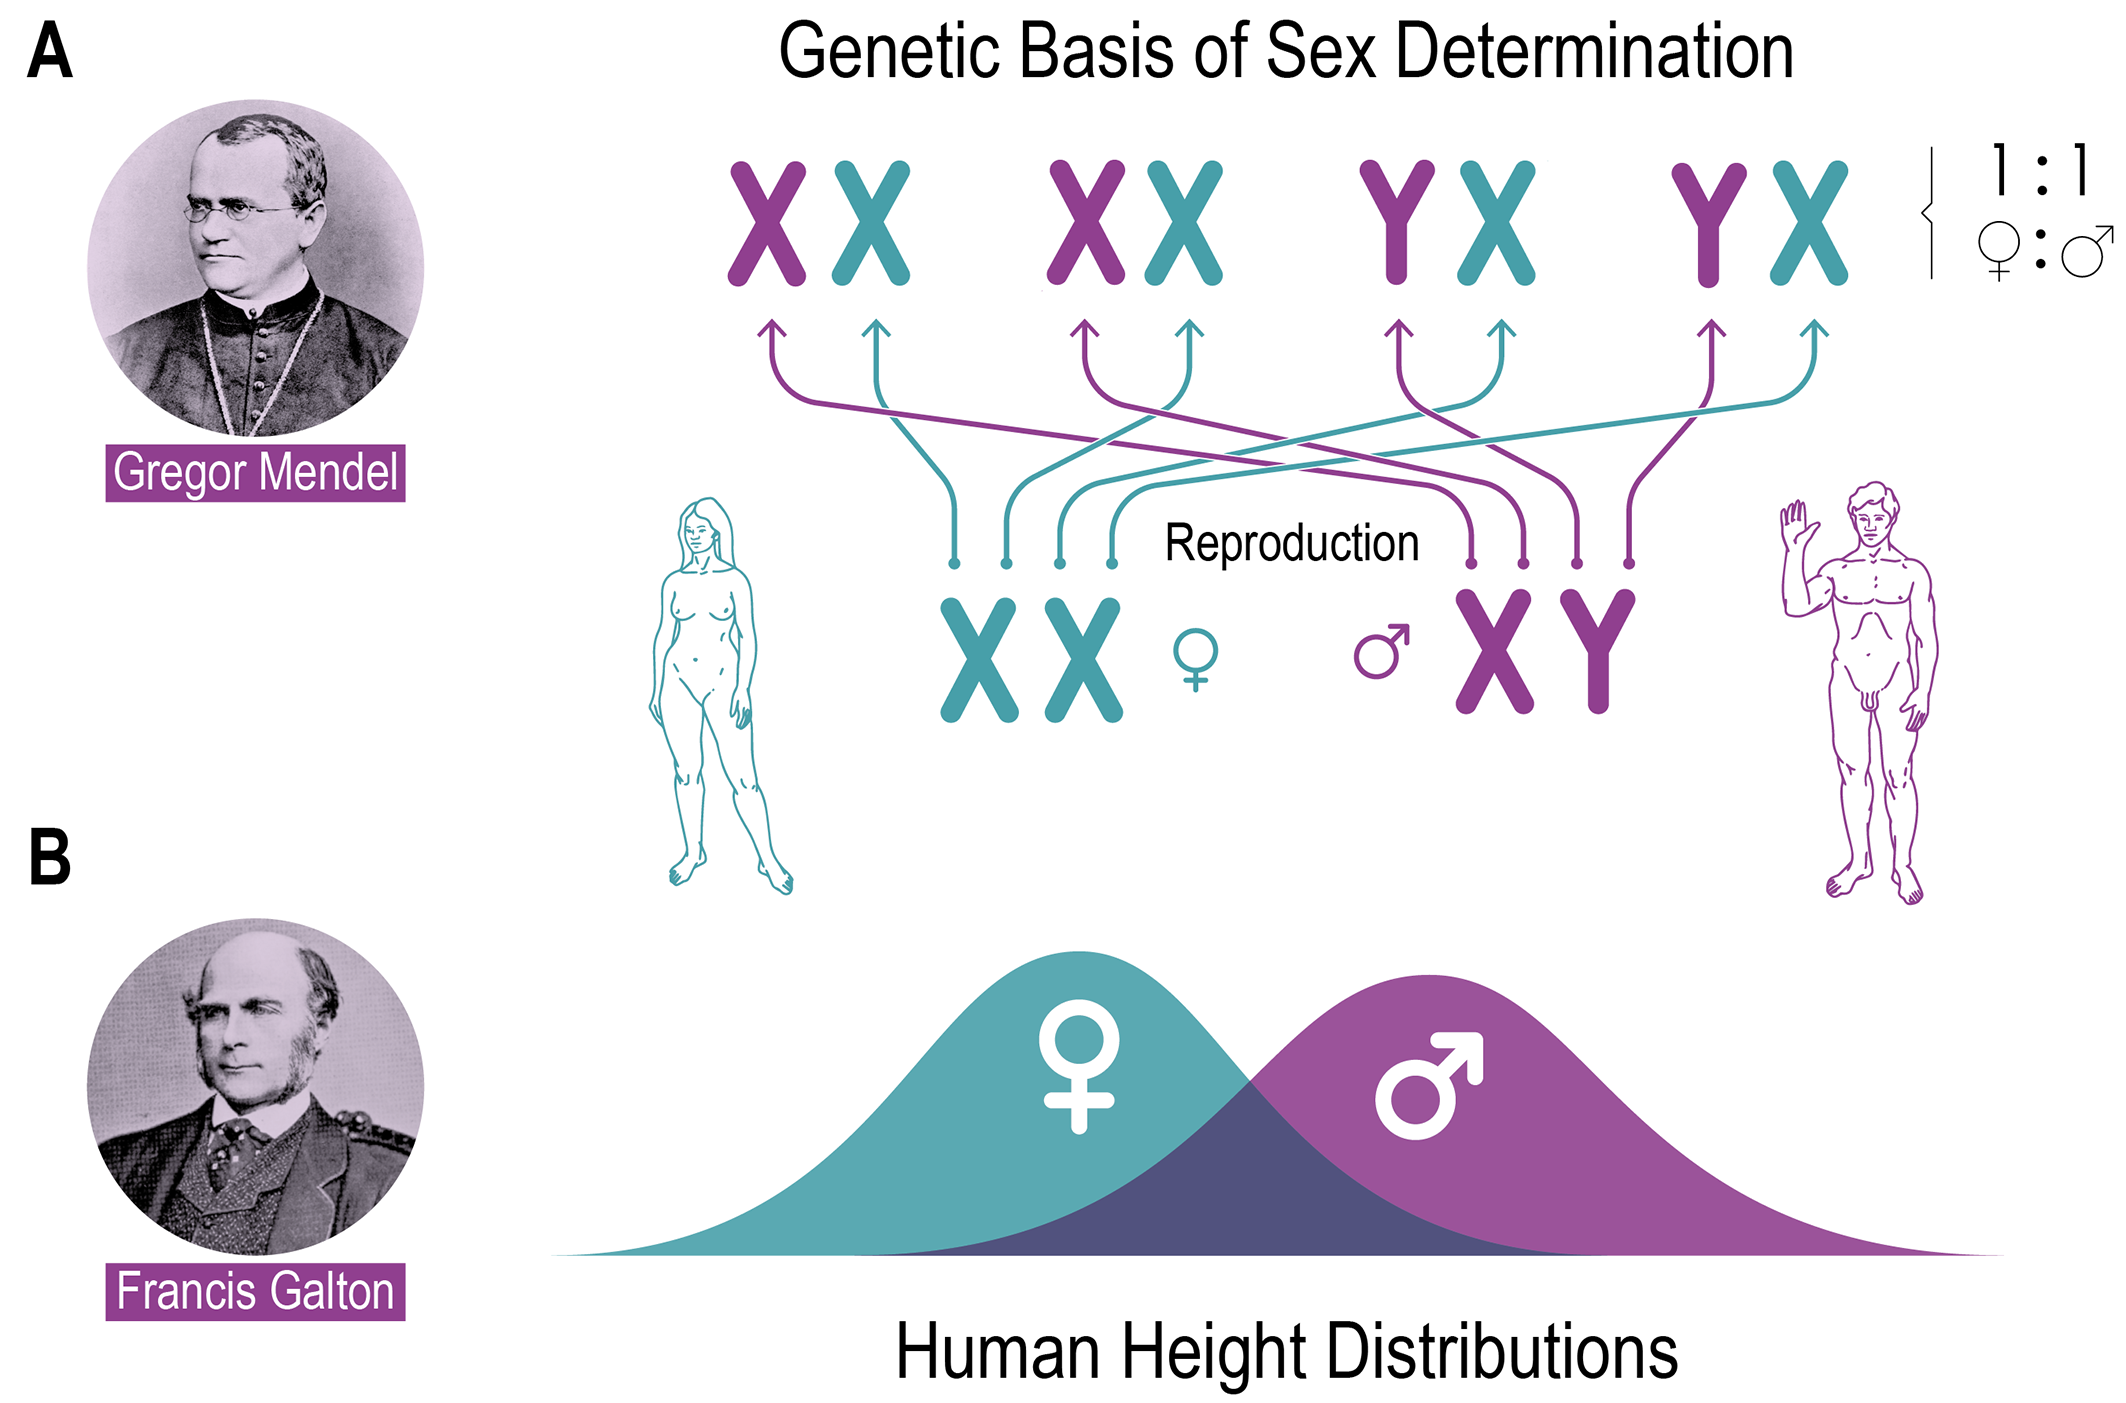
Fig. 1 Comparison of the two genetic concepts in case of sex determination. Panel A shows the Mendelian concept with two discrete sex chromosomes, which combine independently to form the next generation and create two discrete categories of sex. Mixing the gametes according to the Mendelian laws in the next generation recreates the sexes with a 50 % probability each and thus keeps a constant sex ratio with half males, half females in the population. Panel B relates to what follows after this initial step, namely the formation of the actual phenotype according to the principles discovered by Galton. This results in continuous traits that form Gaussian distributions, here shown as the height distributions for females and males. The variance of these traits is generated as a mixture between genetic and environmental factors, which can lead to different averages in the sexes, but with substantial overlap.
A particularly problematic form of discrete thinking has emerged in the discussion around the inheritance of intelligence. The measurement of “intelligence” via intelligence quotient (IQ) tests yields continuous values and any discussion of its heredity should therefore be fully in the realms of Galton’s genetics. But some authors have assigned average IQ values to subpopulations and implicitly treat these as discrete characters for these populations. When this is combined with poorly substantiated claims of differences in average fertility for these population groups, they end up with scenarios of predicted substitutions of populations. But such discrete thinking is alien to quantitative genetics and this line of arguments is therefore wrong on many accounts, even independent of the question whether IQ can be objectively measured. First of all, even if only parents from one end of the distribution would have children, one would still recreate almost the same variance in IQ distribution as before (see Box1, part B). Only the population average could slightly change, and even this would not happen as long as there is at least some population mixing. Further, any prediction on changes of averages depends on the measure of heritability and this is in itself not a constant factor, but depends on the condition under which it is measured (Box 1). Hence, it would dramatically help in such a discussion if the principles of quantitative genetics would be taught in school alongside the principles of Mendelian genetics.
Oligogenic versus Polygenic Concepts
As discussed above, a possible solution to bridge the gap between categorical and continuous phenotypes has been worked out by Fisher (Fisher 1918, 1930). It starts with the realization that if more than one gene contributes to a phenotype, then one gets even under strict Mendelian rules an increasing number of genotype classes. Under a random assortment model, these classes can result in a phenotypic distribution that approximates a Gaussian distribution. For example, if two genes with three alleles each contribute to a phenotype, then the Mendelian mixing of these yields already 9 phenotypic classes (Fig. 2). Hence, from a Mendelian point of view, the problem of continuous traits could simply be solved by considering a mix of a handful of genes, the so-called “oligogenic” model. In this vein, Thoday and Thompson (1976, p. 335) conducted a study starting with the premise:
“Phenotypic distributions indistinguishable from normal distributions are often interpreted as showing the segregation of many genes. Such characters may then be passed over by physiologists and developmental biologists as too complex or otherwise unsuitable for developmental studies.”
to show that the great majority of observed variance could potentially be explained by few loci, which would make it much more accessible to mechanistic studies. This reflects a sentiment of convenience for interpreting genetics that was upheld until recently. But Fisher had proposed a polygenic model that implied the contribution of very many genes, each with very small effects (often called “infinitesimal model” to differentiate it from the oligogenic model). This reflected Galton’s view of very many “particles” that should randomly combine to form a Gaussian distribution (Fig. 2). Unfortunately, for a long time it was almost impossible to experimentally distinguish between these alternatives. Comprehensive experiments could only be done with the advent of the genomic revolution in the past decades, which allowed dense marker screening across the chromosomes. Data coming from such experiments showed that the model of large numbers of loci, each of small effect, turned out to reflect the best interpretation for many characters in every species that have been examined (Flint and Mackay 2009).
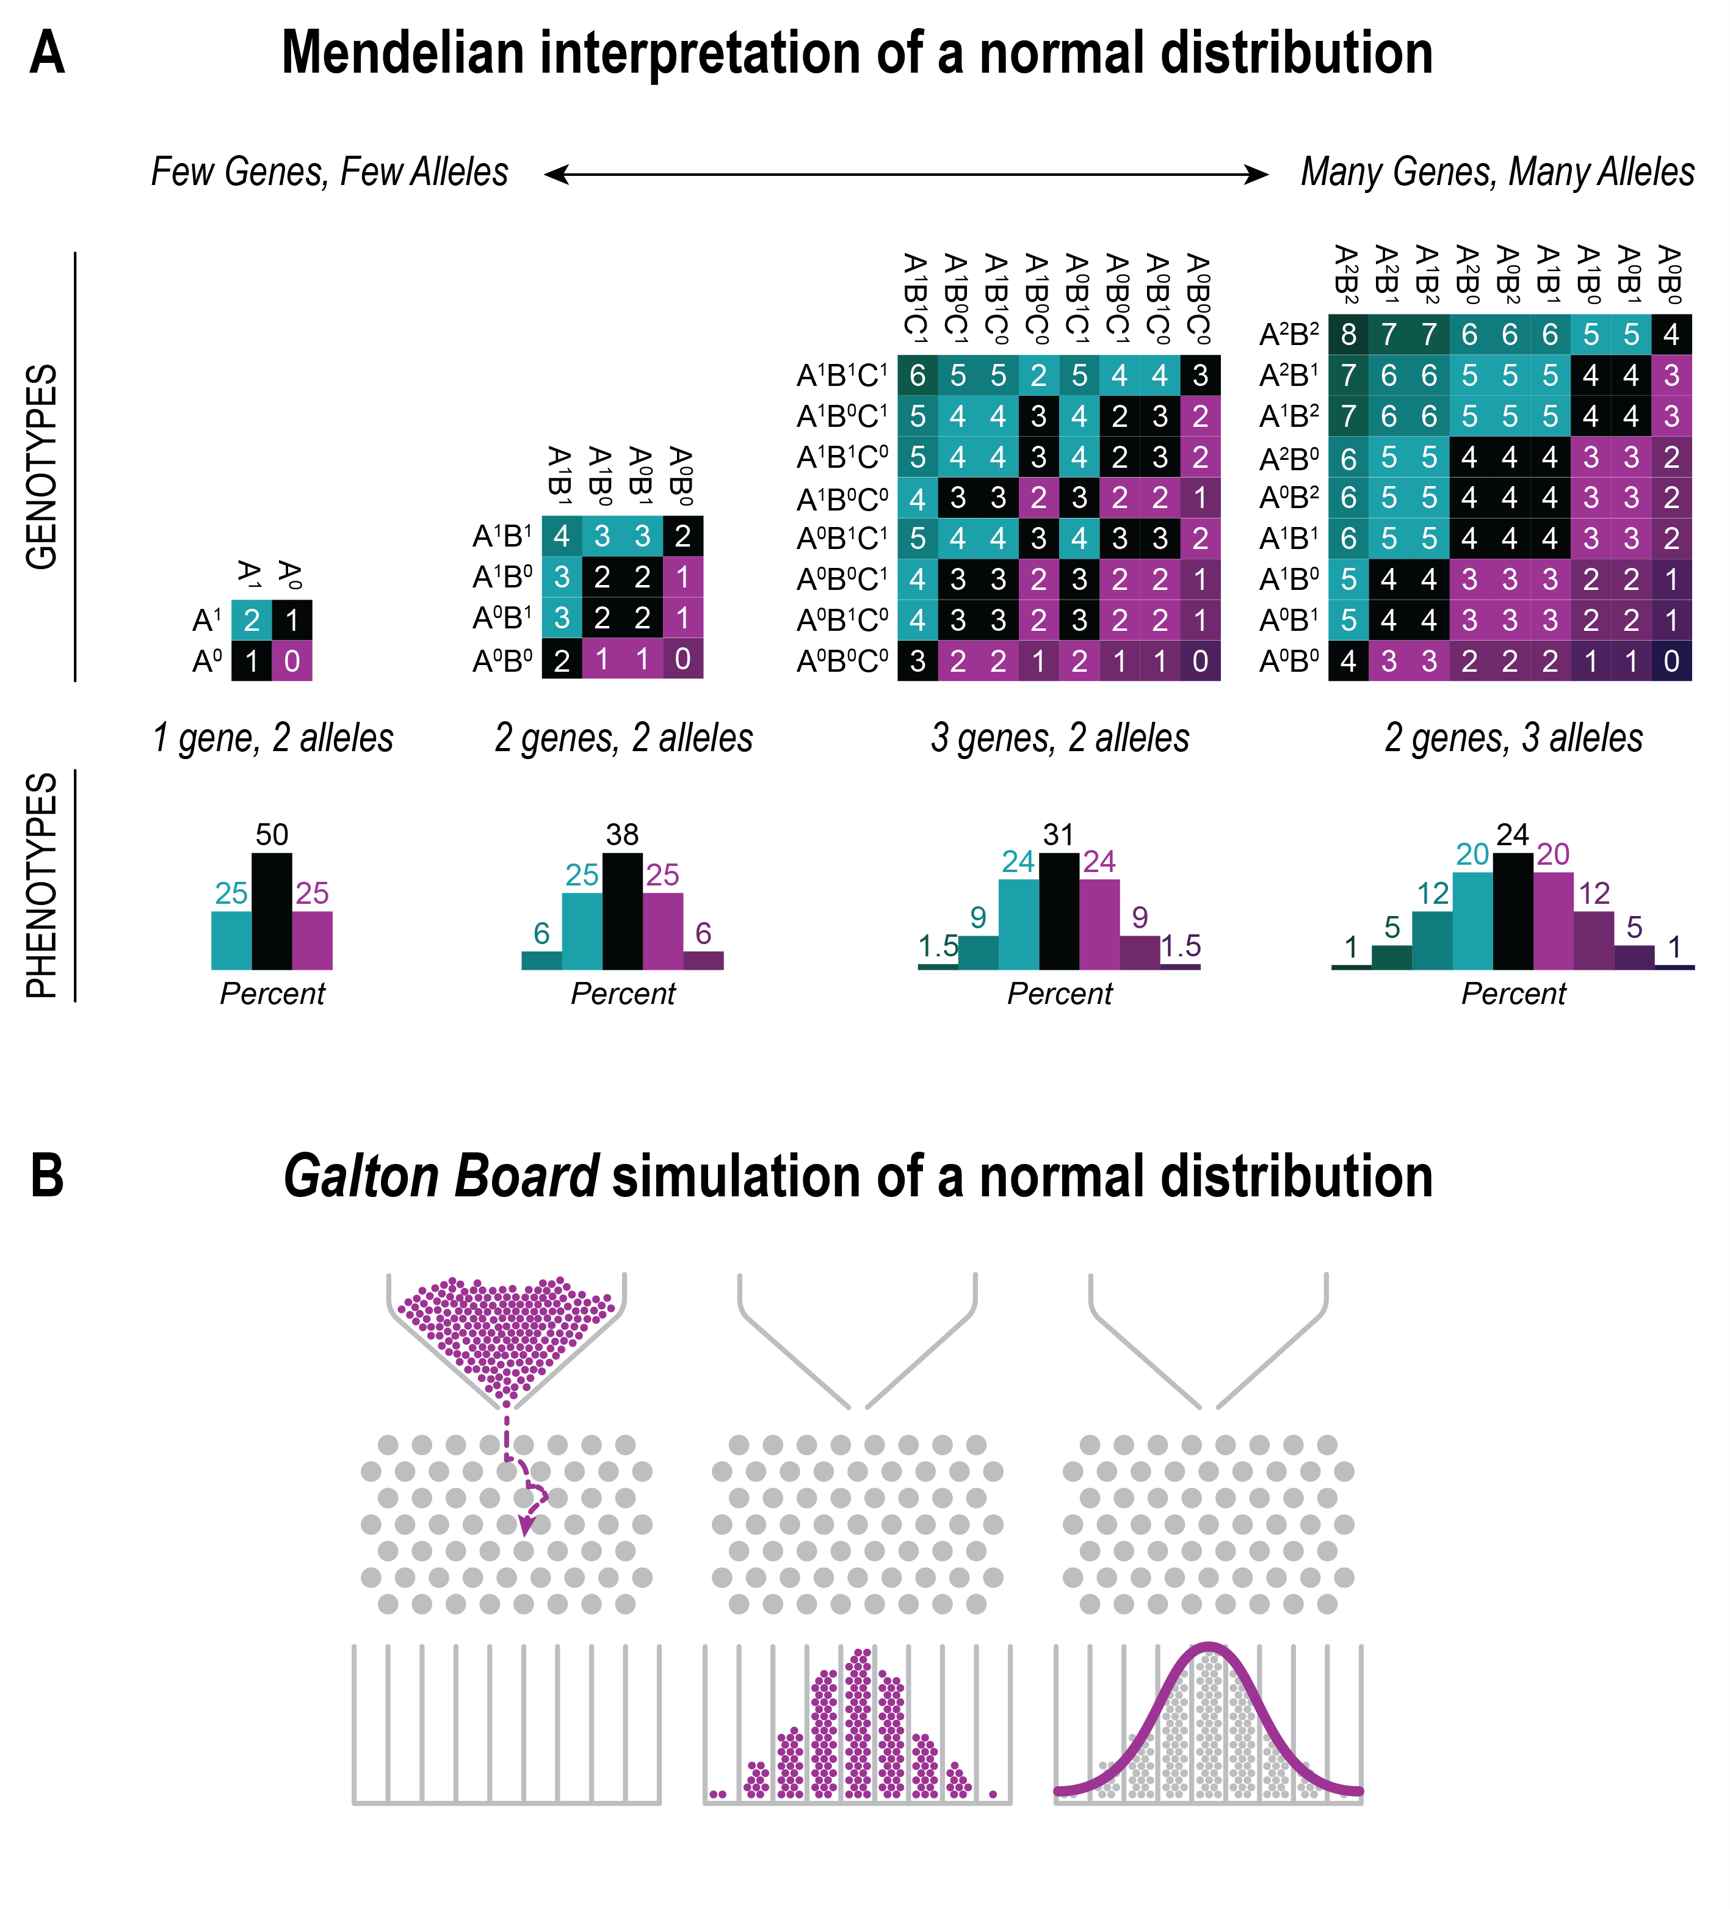
Fig. 2 Comparison of concepts on how the Gaussian distribution of continuous phenotypic measures can be explained. (A) The Mendelian based interpretation under the assumption of the combination of a small number of genes or alleles. (B) The random simulation scheme devised by Galton. Galton first described this apparatus in his book (Galton 1889) (now often called Galton board) to demonstrate basic principles of statistics.
But there is also a further complication. Already Mendel had shown that variants of a gene (alleles) can be dominant over other variants, i.e., in the presence of one copy of a dominant variant, only this has a phenotypic effect. Further, different genes can be epistatic over each other, meaning that the expression of one gene is required to allow another one to have an effect on the phenotype. This is for example the case in a cascade of enzymes that create coat color variants in mice (Silvers 1979). In a polygenic model, both dominance and epistasis lead to many additional possible combinations of phenotypic effects that need to be considered. Although these effects can be incorporated into the infinitesimal model (Barton, Etheridge and Veber 2017), this has the unfortunate consequence that a full statistical treatment becomes next to impossible in real experiments. Hence, one often applies the simplified assumption of all alleles and genes acting only in an additive way. The full statistical treatment of non-additive effects remains therefore one of the great challenges that await a resolution.
Although many refined statistical approaches were devised to interpret the available experimental data in at least one way or the other (i.e., oligogenic or polygenic concepts), the matching of actual genes with quantitative trait phenotypes was an almost unsolvable challenge for decades. Nevertheless, quantitative genetics flourished among breeders because even without knowing the identity or number of the underlying genes, the breederʼs equation (Box 1) allowed them to predict the response to artificial selection and therefore to improve their breeds. Hence, quantitative genetics became extremely important in practical terms since it led to significant improvement of todayʼs plant and animal live stocks that yield our food (Fig. 3A).
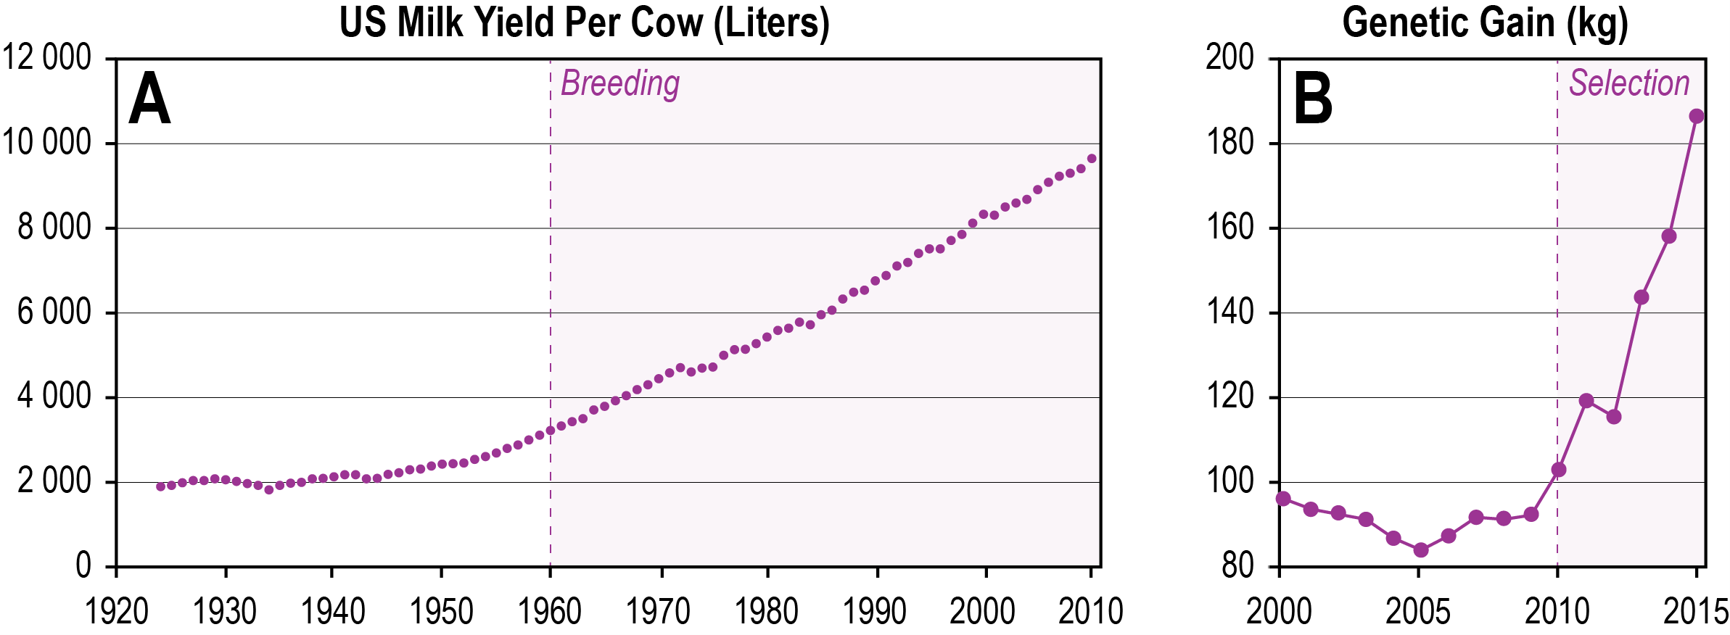
Fig. 3 Impact of quantitative genetics on milk production. (A) The chart represents a plot of liter milk produced per cow per year in the US (Y-axis) in the past hundred years, with the gains due to systematic breeding starting in the 1960s (data from USDA www.nass.usda.gov/Quick_Stats/Lite/). (B) The chart shows the impact of genomic selection on the yearly genetic gain in breeding value for milk yield (kg) (Y-axis), which has started around 2010 (data from Garcia-Ruiz et al. 2016). Note that the relative gain had remained rather constant until then.
The Success of Mendelian Genetics
While quantitative geneticists struggled with finding experimental approaches to identify the genes behind the statistics, the Mendelian approach became extremely fruitful, especially after artificial mutagenesis and recombination mapping were discovered. Mendel used naturally occurring variants of a gene (alleles) for his experiments, but by using artificial mutagenesis (initially either with chemicals or ionizing radiation, nowadays also with directed approaches, e.g. CRISPR/Cas mutagenesis), one could create new variants that do not occur in nature but still serve to study the function of genes. The use of artificial mutagenesis resulted in a genetic paradigm that we may call “knockout genetics”. This paradigm states that the function of a gene is defined through its loss of function. In other words, one has to search for a mutant version of the gene which abolishes its function (a so-called “null allele”). Then, one can compare individuals that carry two copies of the null allele (i.e. homozygous mutants) with non-mutant individuals and infer the function(s) of the gene based on the differences between the two groups of individuals. While this approach has its pitfalls and limitations, it became hugely successful in the past decades given that it provided a practical answer to the question of gene function. This culminated in a research agenda that posited that one should be able to use systematic mutagenesis of all genes in the genome, combined with analyzing them one by one, to find every gene that contributes to a given phenotype (Nolan et al. 2000). In Mendelian thinking, this is a perfectly valid assumption and there are endless examples where this has worked successfully to identify key genes in genetic pathways, up to the Noble prize for unraveling the genetic basis of early development in Drosophila (Nuesslein-Volhard and Wieschaus 1980). Intriguingly, if one would have adopted only Galton’s genetics, one would not even have considered such an approach.
The principles of quantitative genetics are based on genes having naturally occurring functional variants or alleles. This in part explains the common mismatch between genes identified through homozygous knockout studies and genes identified with GWAS for the same trait – even when a gene (or its absence) modifies a trait, it will only be identified in GWAS if it has naturally occurring functional variants that have been sampled.
The success of knockout genetics has led to a peculiar type of dogmatic thinking. It posits that the function of a gene has only been conclusively demonstrated when one has done a knockout, ideally combined with secondary artificial rescue with its wildtype variant. But this dogma is too simple, since it ignores what we know from quantitative genetics. In the polygenic model, none of these genes works in isolation, (very) many are expected to contribute to a given phenotype, implying also that single genes can contribute to many phenotypes (this well-known phenomenon is called pleiotropy). In fact, even the knockout geneticists are perfectly aware that the phenotypic effect of a gene knockout depends on the genetic background of the individual (Chandler, Chari and Dworkin 2013, Sittig et al. 2016) which dictates an experimental paradigm that requires strictly controlled isogenic strains to obtain reproducible results. The concept of the use of isogenic strains was already introduced by the Danish geneticist Wilhelm Johannsen, who coined also the terms "gene", “genotype" and "phenotype". He suggested that the power of isogenic strains lies in studying genetic mechanisms without the confounding effect of the genetic variation between individuals that one finds in natural populations. He argued that since statistical geneticists like Galton and Pearson could not distinguish between phenotypic variation driven by genetic variation or by other sources (e.g. by environmental conditions), their interpretations could be misleading (pp. 132–134 in Johannsen 1909). Most of our genetic knowledge from model systems is therefore based on insights gained with isogenic strains only.
Moreover, loss of the same gene in different species can have different phenotypic consequences. It can be lethal in some species and have almost no effect in other species (Rancati et al. 2018). This implies that the function of a gene is part of a network and the evolution of this can change the core function of the gene. Even individuals in the same species can show very different responses to the loss of a gene. In humans, it is possible to detect cases where a healthy individual is mutant for a gene that would have severe medical consequences in most other individuals (Narasimhan et al. 2016).
Finally, while it is well known in quantitative genetics that environment plays a role in shaping the genetic effects on the phenotype, the Mendelian experimental paradigm tries to cut out the environmental effect as far as possible through standardizing the conditions under which one conducts an analysis. Unfortunately, there are still many misunderstandings, both with respect to experimental agendas, as well as to interpreting data when one takes only the Mendelian genetic paradigm into account.
Genome-Wide Association Studies
Genome-wide association studies (GWAS) have become the key to understand polygenic inheritance. The experimental idea behind them is very simple, but the technical possibilities to run them at a meaningful scale have only recently emerged and are still being improved. The driving factor behind GWAS was the quest to understand the genetics of common genetic diseases in humans and to develop drugs against them.
In the simplest form of a GWAS one would have two groups of individuals from a natural population, one with a phenotype that one wants to map (e.g. a complex disease) the other a wildtype (or disease-free) group. Ideally one would then obtain the genome sequences from all individuals and compare them at every position to see whether certain genetic variants are more prevalent in one group versus the other. One of the main problems to achieve a truly genome-wide search is that full genome sequencing of properly sized cohorts (thousands to hundreds of thousands of individuals) is too expensive. The alternative has been to type all common variants in a population which are much fewer than all positions in the genome. This approach made the first human GWAS possible about 15 years ago (Wellcome Trust Case Control Consortium 2007) and it remains the common standard until now. However, after the initial five years of accumulating data, it seemed that the promises to justify the investment were not met. In particular, the hope to find key genes for drug targeting of common human diseases fell apart and the whole approach started to be questioned. Visscher et al. (2012) provide an account of the common critique at that time and respond to it. But regardless of what impact GWAS results have had on understanding complex genetic diseases, it is nonetheless clear that they have led to a revolution in genetics and biology.
Lessons from Human Height Studies
A natural trait that has changed our thinking in terms of single gene effects versus polygenic genetic architectures is human height. Galton’s work had paved the way for its genetic analysis, but the question of which actual genes are involved in its regulation remained open. Physiologists had found in the 1950s a single hormone, somatotropin, that can control the body size of mammals in a concentration depended way. But how would such concentration differences come about in natural populations? It would require a multitude of alleles of the gene that should segregate in the populations in a way to create a continuous distribution. But this does not match with what we know about segregating alleles of a gene – most genes have only a few functional variants in an average population.
In humans, height was an ideal model trait to develop techniques and procedures for large-scale genome-wide studies. The trait can be objectively measured in large cohorts, its heritability is very high, experimental analyses can be scaled and data can be easily combined from different studies.
A first comprehensive study was published in 2010 and showed that variants in at least 180 loci contribute to human height (Allen et al. 2010). A later meta-analysis of several human height studies including data from more than 250,000 individuals was published in 2014 (Wood et al. 2014). It provided unequivocal evidence that human height is indeed controlled by very many genes with many naturally segregating alleles. The authors identified at least 423 loci in multiple biochemical pathways, with thousands of causal variants. They concluded: “Our results indicate a genetic architecture for human height that is characterized by a very large but finite number (thousands) of causal variants.” (Wood et al. 2014). But although this showed very clearly a highly polygenic architecture, even this conclusion was still somewhat premature. They struggled with a problem that has turned up in practically all GWAS, namely that the sum of genetic effects calculated from the identified variants did not fully explain the observed heritability of the phenotype. The explanation for such a pattern was left open to speculation. In the meantime it has become clear that this “missing heritability” problem (Manolio et al. 2009) is mostly due to self-constraints in the experimental strategy and the statistical analysis, and although there have been many viewpoints of how the missing heritability in GWAS could be explained (Eichler et al. 2010) it is now assumed that it has mostly two major reasons.
The first is the statistical significance cutoff for calling an allele significantly associated with a phenotype (Yang et al. 2010). These cutoffs are chosen under the assumption that most of the association signals are noise and only a few can be real – an assumption that is grounded in the oligogenic view. Hence, one uses extremely strict statistical correction procedures to minimize the perceived chance of detecting “wrong” or only weak associations. But the polygenic view assumes that the phenotypes are caused by very many real, albeit small, effects. In fact, it can be shown that by not imposing a cutoff and simply adding up all association effects, one can much better explain the full heritability (Visscher et al. 2014, Yang et al. 2011).
Boyle et al. (Boyle, Li and Pritchard 2017) have taken this principle to the extreme, combined it with further genomic and phenotype data and concluded that basically every gene expressed at the relevant time of development could be involved in a given phenotype such as human height, albeit with different effect sizes (Fig. 4). They have called this the “omnigenic” model of quantitative traits, which claims that the sum of the influence of small effect genes (mostly regulatory ones) can be larger than the sum of the effects of genes in core pathways. Hence, this finally suggests that Fisher’s infinitesimal model may not just be an abstract assumption, but could have a true biologic meaning.
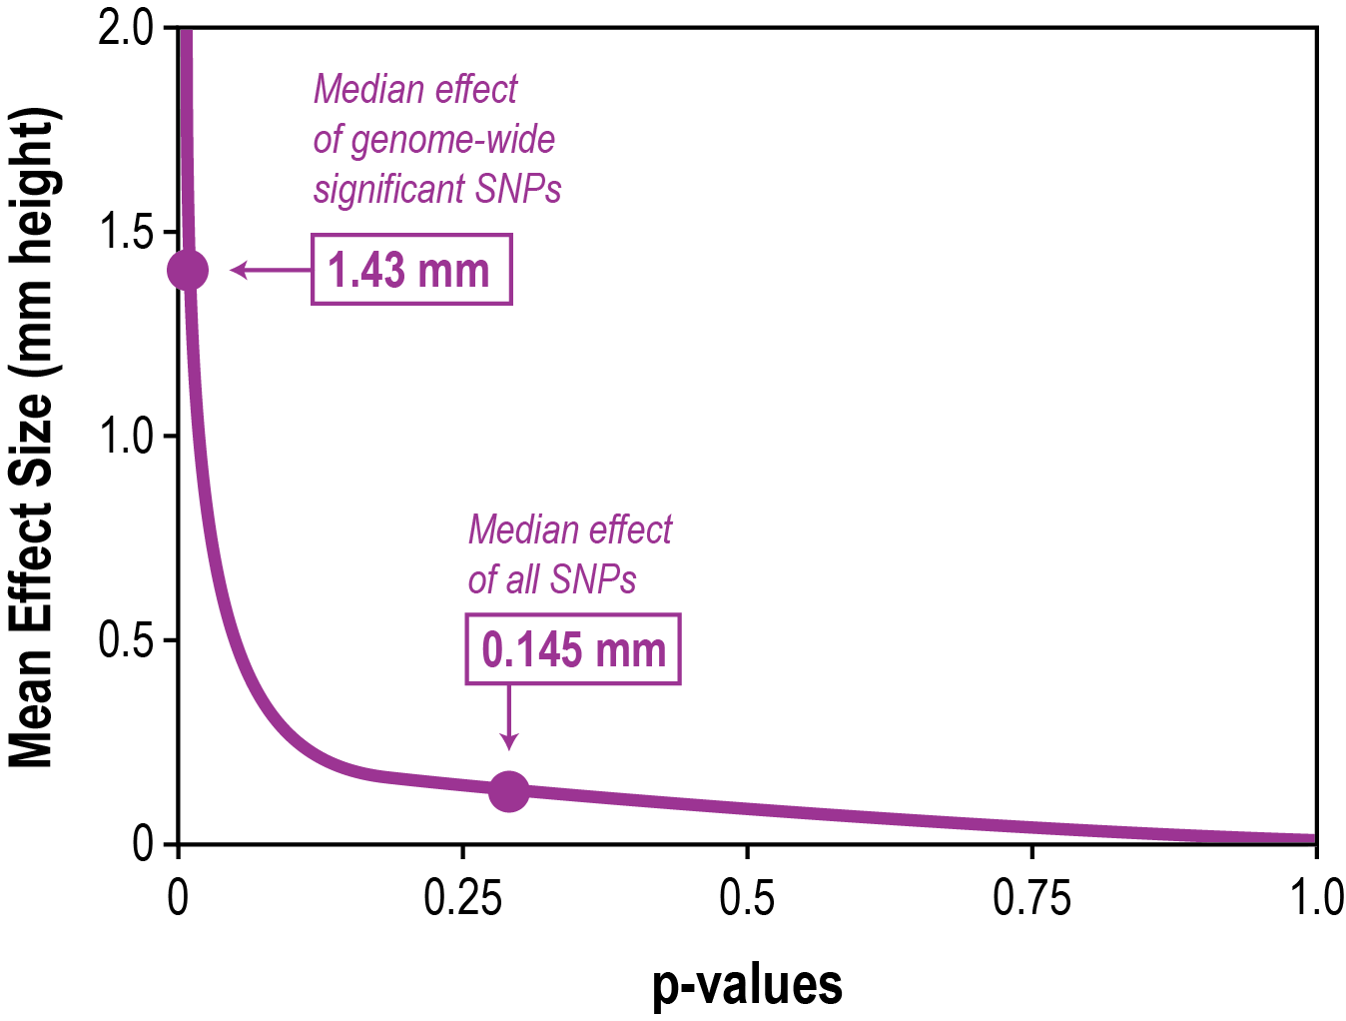
Fig. 4 Distribution of SNP effect sizes for human height data. The graph shows that there are genetic variants (SNPs) that have strong effect on human height and these receive very high statistical support, such that they are considered as significant. The majority of genetic variants would not be considered to be significant, but can still be calculated to have an effect on size. Since these low effect SNPs are much more abundant than the large ones, they determine in total more of the final height of an individual. Figure redrawn from (Boyle et al. 2017).
But the data show also that there are still only a few alleles with large effects and a tail of many alleles with increasingly smaller effects. Interestingly, however, alleles with large effects tend to be rare, which has raised the possibility that they may actually be deleterious alleles that would be lost over time due to negative selection. Experimental studies in yeast support this conclusion by showing that alleles with particularly strong effects in QTL experiments tend to be new mutations that are selected against and are therefore rare in populations (Bloom et al. 2019, Fournier et al. 2019).
This brings us to the second reason for the “missing heritability” problem, namely the filtering out of low frequency alleles from standard datasets. Again, because of technical considerations (mostly related to the probability of linkage with causal variants and statistical power), only those alleles that segregate with frequencies of more than 5 % in a population (i.e. common variants) are included in standard GWAS analysis. But this excludes the alleles that could have a particularly high impact on the phenotype (Pallares 2019).
Both, the omnigenic model, as well as the explanation for the missing heritability are still under discussion, and it is to be expected that new insights will emerge over time. An additional complication that has emerged in all GWAS is that associations may be created by indirect effects, namely non-random structure in the populations and/or hidden genetic relationships. The linkage disequilibrium effects measured through GWAS have been demonstrated to be very sensitive to population structure and this obscures also signals of selection on phenotypes (Barton, Hermisson and Nordborg 2019, Berg et al. 2019, Sohail et al. 2019). While the current statistical analysis pipelines try to take care of this, the problem still needs more attention in the future, especially in the context of the omnigenic model (Barton, Hermisson and Nordborg 2019, Wray et al. 2018).
Genomic Selection
Scientists involved in livestock breeding were probably the first to accept the idea of a highly polygenic basis for quantitative traits, especially those traits that are relevant for commercial exploitation. However, until about 20 years ago, breeders would consider up to several hundred genes already as highly polygenic. Now it is commonly accepted that a large proportion of genes in the genome (in the order of 10,000) may contribute to a given trait. However, the individual effect sizes of these genes are too small to pinpoint them unequivocally and to use them for marker assisted breeding programs. This insight led to a radically new proposal for predicting breeding values of individuals. When most genes in the genomes contribute to a trait, then one could simply use dense marker information across the whole genome to predict the genetic value of an individual for the trait in question (Meuwissen, Hayes and Goddard 2001). In practice, one trains a model based on a set of animals that had been phenotyped before, along with their associated genetic data. With this information, one can then make predictions for a new set of non-phenotyped individuals of the same breeding stock, simply by genotyping them for the same markers. In the case of dairy cow production, this approach leads to tremendous time savings, since the breeding values for bulls in terms of milk production could so far be assessed only from their daughters, i.e. with at least one generation delay (Garcia-Ruiz et al. 2016). The impact on genetic gain was directly measurable after genomic selection regimes were implemented into the dairy cow breeding programs (Fig. 3B). This general principle was found to be widely useful in breeding programs, both for animals and plants (Crossa et al. 2017, Meuwissen, Hayes and Goddard 2016). Hence, accepting the implications for a highly polygenic nature of quantitative traits has led to a revolution in breeding procedures, the results of which are currently coming to the markets.
Evidently, the technology for high-density marker screening that is at the base of genomic selection procedures, was developed as part of the human genome project. That it would have its most immediate consequences in livestock breeding was not predictable. In the coming years, genome selection procedures will also profit from the developments in artificial intelligence, as well as automated phenotyping, since the training part is crucial to make the best predictions of breeding values (Koltes et al. 2019).
Medical Studies versus Basic Biology Studies
It is necessary to make a distinction between medically motivated GWAS that aim to unravel disease risk phenotypes and GWAS aiming to understand basic principles of biology, like the genetic basis of variation in non-disease phenotypes. Diseases with a genetic basis are usually caused by deleterious mutations, or by variants that have come into mismatch with their environments. But when studying naturally occurring variation in non-disease phenotypes, one is primarily interested in genetic variants that have passed through an adaptive phase and that are subject to stabilizing selection. This makes not only a difference for testable expectations, but also a difference for choosing cohorts, experimental designs and interpretation of the data.
In medically motivated studies it has become the norm that any particular GWAS finding should be replicated in a separate cohort to ensure that it is not a statistical artefact (Chanock et al. 2007). While this is a well-justified cautionary procedure, it does not take into account that a given allele may have different effects in different genetic backgrounds, i.e. one is most likely filtering out possibly interesting associations when the control cohort is genetically different. Basic sciences should be particularly interested in such effects to better understand the genetic architecture as a whole, i.e. the replicability in a different cohort cannot be used as a required standard.
Another problem points to publication bias and funding availability. Studies that find major effect loci are more attractive to prominent journals than studies that uncover a complex genetic architecture with many loci of very small effect. This, in turn, results in more funding going to research programs that focus on traits with simple genetic architectures. The unfortunate consequence of this feedback loop is the impression that for non-disease phenotypic variation the ideal result is to find major effect loci. However, such expectations might not at all be aligned with evolutionary realistic scenarios (Rockman 2011). It is now rather clear that most natural phenotypes have a polygenic underpinning and that major effect loci are exceptions in special circumstances.
The Role of Model Organisms
Questions have now arisen in how far results from model organisms can help studies in humans. Visscher (Visscher 2016, p. 378) has stated in a comment on the future of human complex trait genetics:
“I would also argue that model organisms have been largely unsuccessful in modeling complex traits in general, whether for proposed applications in human health or for potential applications in plant and animal breeding.”
One can indeed take such a view. However, the work on model organisms was mostly done within the Mendelian genetic paradigm, and it has unraveled all the mechanisms of basic biology on which also human genetics is based. Hence, the general value of studies in model organisms is undisputed in this respect (Lehner 2013). But this work has indeed yielded only few new insights into complex traits. Actually, when the function of genes and alleles is highly background dependent, one should not even expect that complex trait results obtained in model organisms can be easily transferred to humans. Still, associations with major biochemical pathways should be reasonably conserved. For example, work on genes determining body size in mice has revealed an association with a growth control pathway (mTOR) (Chan et al. 2012), which was then also found to be a major pathway contributing to size in humans (Wood et al. 2014). However, one has to expect that different genes of the core pathways will be detected through the GWAS approach, since it is based on the natural variants that segregate in a given population at a given time. Hence, a gene that could be detected as a key gene through knockout genetics may be missed in a GWAS simply because it does not have different functional alleles in the given test population. Interestingly, in Drosophila it was conversely shown that the knockout of randomly chosen genes can influence the variance of a quantitative trait in the same way as naturally segregating alleles of genes identified by GWA, supporting a complex omnigenic model (Zhang, Reeves and Tautz 2021).
The Genotype-Phenotype Map
The question of how the information in the genome is used to create a three-dimensional living organism (i.e. its natural phenotype) remains frustratingly poorly understood. While we have a good insight into the earliest processes of development where stem cells are formed and germ layers as well as organs are established, there is very little understanding of how development proceeds from then onwards, especially with respect to integrating and connecting organs and to establish the shape of the individual. Despite much genetic and environmental perturbation, phenotypes of individuals are robustly created during development (Felix and Barkoulas 2015), a phenomenon called canalization by (Waddington 1957). And, at the population level, the regulation of the variance around the mean phenotype presents another level of canalization (Gibson and Lacek 2020). Controlling such variance, initially interpreted as noise, not only at the developmental level but also in adult phenotypes may itself have a genetic basis (Duveau et al. 2018, Richard and Yvert 2014) and therefore have fundamental implications for the evolutionary process (Wagner 2007).
In view of polygenic genetics, it is actually a formidably complex problem to understand how a phenotype is generated. For example, the building of the skull of vertebrates requires an end product of high precision, where the senses (eyes, ears, nose) are properly integrated into functional units and where the feeding apparatus is optimized to deal most efficiently with the available food. At the same time, many genetic variants segregate in any population that modify the skull shape, but keep it functional in most combinations of alleles. Furthermore, the skull is also a major target of adaptive evolution, i.e. it can very easily be evolutionarily modified to respond to new food sources, new requirements for sensory reception or sexually selected modifications. The polygenic model suggests now that all these phenotypic aspects should be dependent on a large overlapping set of genes and alleles. How do they achieve the necessary integration, while remaining evolutionarily highly flexible? If anything, these insights make the mechanisms for establishing the genotype-phenotype map even more mysterious than before. This remains therefore one of the largest challenges in biology. It is equally a challenge for geneticists, as well as for developmental and evolutionary biologists.
In evolutionary biology the currently largest problem is to understand how adaptive selection works to shape the phenotype. Although Fisher has already provided a comprehensive treatment of this question in his 1930 book, the question of whether single loci are the main drivers of adaptation, or whether the infinitesimal model is a more appropriate model was left open for discussion. Given the technical limitations to study polygenic evolution, most current evolutionary studies and selection models on adaptation are based on single or few loci. Shaping them into new statistical tools for studying polygenic selection has only recently been taken on again (Barghi, Hermisson and Schlotterer 2020, Barton, Etheridge, and Veber 2017, Jain and Stephan 2017). This may even require a "New Synthesis", as Barton (Barton 2022) put it recently:
"Yet, the [evolutionary] synthesis remains unfinished. We do not understand why sexual reproduction and a fair meiosis predominate in eukaryotes, or how far these are responsible for their diversity and complexity...and we still do not have a good framework for understanding polygenic variation or diffuse function."
Outlook
For more than 100 years, the two different views on genetics have been developed with very little experimental overlap. So, what are the chances to understand polygenic genetics in Mendelian mechanistic terms? GWAS have now at least provided candidate loci and are getting increasingly closer to identify candidate mutations that contribute to phenotypes. These can then theoretically serve to test them one by one with classic experimental paradigms. But is this realistic for 1000+ loci, of which each contributes only a 1000th to the phenotype – and is dependent on environmental conditions?
An experimental approach towards polygenic genetics are selection experiments. These are started from a population of individuals that all carry different natural alleles from which a phenotype of interest is selected for multiple generations. Almost any quantitative trait can be changed by continuously selecting a subset of animals from a phenotypic range distribution as parents for the next generations. The frequency of alleles involved in shaping the phenotype are expected to change in a continuous direction with every generation under selection. By comparing the start frequency of alleles with the end frequencies, one has the prospect to identify the genes that have contributed to the selected phenotype. However, allele frequency changes can also occur by random drift, especially since selection entails also some form of genetic bottleneck. To better distinguish between such random effects and the directed effects, one can set up parallel lines of selection as replicates. One can then expect that the random effects cancel each other out in the parallels, while the directed effects remain.
Although the possible power of parallel selection has long been realized (Falconer 1973), the need for high density genotyping to evaluate all genetic variation has impeded its application. This has changed in the past decade with the increasing availability of high-density SNP arrays and nowadays with the option to use whole genome sequencing data for genotyping. Proof of principle experiments have emerged that confirmed the power of parallel selection to map complex traits (Barghi et al. 2019, Castro et al. 2019, Chan et al. 2012, Huang et al. 2018, Long et al. 2015). Hence, rather than just describing genetic associations with phenotypes, one has a tool that is based on experimentally manipulating a phenotype in a polygenic context.
However, all of these approaches still rely on naturally segregating alleles, which were shaped by evolutionary processes. One of the powers of the classic genetic approach is the generation of random unbiased mutants for phenotypic analysis. It may therefore be profitable to combine association studies with mutagenesis experiments. For example, if the base population for an association study is derived from a mutagenesis experiment of an inbred strain, rather than from wildtype variation, one has the possibility to link random unbiased mutations to a phenotype of interest. By doing this in independent mutagenesis experiments, one should be able to unravel the components of the network that contribute to the phenotype in a systematic way. This may eventually provide a bridge between the genome wide natural variation examined in GWAS and the more limited synthetic variation that forms the basis of Mendelian studies.


Acknowledgements
We thank Derek Caetano-Anolles for drawing the figures in a consistent design. We thank Christian Jung for his constructive comments on the first version of this publication.
References
Allen, H. L., Estrada, K., Lettre, G., Berndt, S. I., Weedon, M. N., Rivadeneira, F., Willer, C. J., Jackson, A. U., Vedantam, S., Raychaudhuri, S., et al.: Hundreds of variants clustered in genomic loci and biological pathways affect human height. Nature 467/7317, 832–838 (2010). doi:10.1038/nature09410
Barghi, N., Hermisson, J., and Schlotterer, C. Polygenic adaptation: a unifying framework to understand positive selection. Nature Reviews Genetics 21/12, 769–781 (2020). doi:10.1038/s41576-020-0250-z
Barghi, N., Tobler, R., Nolte, V., Jaksic, A. M., Mallard, F., Otte, K. A., Dolezal, M., Taus, T., Kofler, R., and Schlötterer, C. Genetic redundancy fuels polygenic adaptation in Drosophila. Plos Biology 17/2 (2019). doi:10.1371/journal.pbio.3000128
Barnett, A. G., van der Pols, J. C., and Dobson, A. J.: Regression to the mean: what it is and how to deal with it. International Journal of Epidemiology 34/1, 215–220 (2005). doi:10.1093/ije/dyh299
Barton, N., Hermisson, J., and Nordborg, M.: Population Genetics: Why structure matters. eLife 8 (2019). doi:10.7554/eLife.45380
Barton, N. H.: The "New Synthesis". Proc Natl Acad Sci U S A 119/30, e2122147119 (2022). doi:10.1073/pnas.2122147119
Barton, N. H., Etheridge, A. M., and Veber, A.: The infinitesimal model: Definition, derivation, and implications. Theoretical Population Biology 118, 50–73 (2017). doi:10.1016/j.tpb.2017.06.001
Berg, J. J., Harpak, A., Sinnott-Armstrong, N., Joergensen, A. M., Mostafavi, H., Field, Y., Boyle, E. A., Zhang, X., Racimo, F., Pritchard, J. K., Coop, G.: Reduced signal for polygenic adaptation of height in UK Biobank. eLife 8 (2019). https://doi.org/10.7554/eLife.39725
Berry, A., and Browne, J.: Mendel and Darwin. Proc Natl Acad Sci U S A 119/30, e2122144119 (2022). https://doi.org/10.1073/pnas.2122144119
Blakemore, S. J.: The social brain in adolescence. Nature Reviews Neuroscience 9/4, 267–277 (2008). doi:10.1038/nrn2353
Bloom, J. S., Boocock, J., Treusch, S., Sadhu, M. J., Day, L., Oates-Barker, H., and Kruglyak, L. Rare variants contribute disproportionately to quantitative trait variation in yeast. eLife 8 (2019). https://doi.org/10.7554/eLife.49212
Boyle, E. A., Li, Y. I., and Pritchard, J. K.: An expanded view of complex traits: From polygenic to omnigenic. Cell 169/7, 1177–1186 (2017). doi:10.1016/j.cell.2017.05.038
Bradshaw, A. D.: Evolutionary significance of phenotypic plasticity in plants. Advances in Genetics 13, 115–155 (1965)
Castro, J. P. L., Yancoskie, M. N., Marchini, M., Belohlavy, S., Hiramatsu, L., Kučka, M., Beluch, W. H., Naumann, R., Skuplik, I., Cobb, J., Barton, N. H., Rolian, C., and Chan, Y. F.: An integrative genomic analysis of the Longshanks selection experiment for longer limbs in mice. eLife 8 (2019). doi:10.7554/eLife.42014
Chan, Y. F., Jones, F. C., McConnell, E., Bryk, J., Buenger, L., and Tautz, D.: Parallel selection mapping using artificially selected mice reveals body weight control loci. Current Biology 22/9, 794–800 (2012). doi:10.1016/j.cub.2012.03.011
Chandler, C. H., Chari, S., and Dworkin, I.: Does your gene need a background check? How genetic background impacts the analysis of mutations, genes, and evolution. Trends in Genetics 29/6, 358–366 (2013). doi:10.1016/j.tig.2013.01.009
Chanock, S. J., Manolio, T., Boehnke, M., Boerwinkle, E., Hunter, D. J., Thomas, G., Hirschhorn, J. N., Abecasis, G., Altshuler, D., Bailey-Wilson, J. E., Brooks, L. D., Cardon, L. R., Daly, M., Donnelly, P., Fraumeni, J. F. Jr, Freimer, N. B., Gerhard, D. S., Gunter, C., Guttmacher, A. E., Guyer, M. S., Harris, E. L., Hoh, J., Hoover, R., Kong, C. A., Merikangas, K. R., Morton, C. C., Palmer, L. J., Phimister, E. G., Rice, J. P., Roberts, J., Rotimi, C., Tucker, M. A., Vogan, K. J., Wacholder, S., Wijsman, E. M., Winn, D. M., and Collins, F. S.: Replicating genotype-phenotype associations. Nature 447/7145, 655–660 (2007). doi:10.1038/447655a
Crossa, J., Perez-Rodriguez, P., Cuevas, J., Montesinos-Lopez, O., Jarquin, D., de los Campos, G., Burgueño J, González-Camacho, J. M., Pérez-Elizalde, S., Beyene, Y., Dreisigacker, S., Singh, R., Zhang, X., Gowda, M., Roorkiwal, M., Rutkoski, J., and Varshney, R. K.: Genomic Selection in Plant Breeding: Methods, Models, and Perspectives. Trends in Plant Science 22/11, 961–975 (2017). doi:10.1016/j.tplants.2017.08.011
Darwin, C.: On the Origin of Species by Means of Natural Selection. Or the Preservation of Favored Races in the Struggle for Life. London: Murray 1859
Deary, I. J., Cox, S. R., and Hill, W. D.: Genetic variation, brain, and intelligence differences. Molecular Psychiatry 27/1, 335–353. (2022) doi:10.1038/s41380-021-01027-y
Duveau, F., Hodgins-Davis, A., Metzger, B. P., Yang, B., Tryban, S., Walker, E. A., Lybrook, T, and Wittkopp, P. J.: Fitness effects of altering gene expression noise in Saccharomyces cerevisiae. eLife 7 (2018). doi:10.7554/eLife.37272
Eichler, E. E., Flint, J., Gibson, G., Kong, A., Leal, S. M., Moore, J. H., and Nadeau, J. H.: Missing heritability and strategies for finding the underlying causes of complex disease. Nature Reviews Genetics 11/6, 446–450 (2010). doi:10.1038/nrg2809
Einstein, A., and Infeld, L.: The evolution of physics: the growth of ideas from early concepts to relativity and quanta. Cambridge University Press (1938)
Falconer, D. S.: Replicated selection for body weight in mice. Genetics Research 22/3, 291–321 (1973). doi:10.1017/s0016672300013094
Felix, M. A., and Barkoulas, M.: Pervasive robustness in biological systems. Nature Reviews Genetics 16/8, 483–496 (2015). https://doi.org/10.1038/nrg3949
Fisher, R. A.: The correlation between relatives on the supposition of Mendelian inheritance. Transactions of the Royal Society of Edinburgh 52, 399–433 (1918)
Fisher, R. A.: The Genetical Theory of Natural Selection. Oxford: Clarendon Press 1930
Flint, J., and Mackay, T. F. C.: Genetic architecture of quantitative traits in mice, flies, and humans. Genome Research 19/5, 723–733 (2009). doi:10.1101/gr.086660.108
Fournier, T., Abou Saada, O., Hou, J., Peter, J., Caudal, E., and Schacherer, J.: Extensive impact of low-frequency variants on the phenotypic landscape at population-scale. eLife 8 (2019). doi:10.7554/eLife.49258
Galton, F.: Natural Inheritance. London: Macmillan 1889
Ganna, A., Verweij, K. J. H., Nivard, M. G., Maier, R., Wedow, R., Busch, A. S., Abdellaoui, A., Guo, S., Sathirapongsasuti, J. F.; 23andMe Research Team; Lichtenstein, P., Lundström, S., Långström, N., Auton, A., Harris, K. M., Beecham, G. W., Martin, E. R., Sanders, A. R., Perry, J. R. B., Neale, B. M., and Zietsch, B. P.: Large-scale GWAS reveals insights into the genetic architecture of same-sex sexual behavior. Science 365/6456 (2019). doi:10.1126/science.aat7693
Garcia-Ruiz, A., Cole, J. B., VanRaden, P. M., Wiggans, G. R., Ruiz-Lopez, F. J., and Van Tassell, C. P.: Changes in genetic selection differentials and generation intervals in US Holstein dairy cattle as a result of genomic selection. Proceedings of the National Academy of Sciences of the United States of America 113/28, E3995–E4004 (2016). https://doi.org/10.1073/pnas.1519061113
Gibson, G., and Lacek, K. A.: Canalization and robustness in human genetics and disease. Annual Review of Genetics 54, 189–211 (2020). doi:10.1146/annurev-genet-022020-022327
Gupta, A. P., and Lewontin, R. C.: A study of reaction norms in natural-populations of drosophila-pseudoobscura. Evolution, 36/5, 934–948 (1982). 10.1111/j.1558-5646.1982.tb05464.x
Hartfield, M., and Keightley, P. D.: Current hypotheses for the evolution of sex and recombination. Integrative Zoology 7/2, 192–209 (2012). 10.1111/j.1749-4877.2012.00284.x
Hernstein, R., and Murray C.: The Bell Curve: Intelligence and Class Structure in American Life. New York (NY, USA): Free Press 1994
Huang, J., Li, J., Zhou, J., Wang, L., Yang, S. H., Hurst, L. D., Li, W. H., and Tian, D. C.: Identifying a large number of high-yield genes in rice by pedigree analysis, whole-genome sequencing, and CRISPR-Cas9 gene knockout. Proceedings of the National Academy of Sciences of the United States of America 115/32, E7559–E7567 (2018). doi:10.1073/pnas.1806110115
Jain, K., and Stephan, W.: Modes of rapid polygenic adaptation. Molecular Biology and Evolution 34/12, 3169–3175 (2017). doi:10.1093/molbev/msx240
Joel, D., Garcia-Falgueras, A., and Swaab, D.: The complex relationships between sex and the brain. Neuroscientist 26/2, 156–169 (2020). doi:10.1177/1073858419867298
Johannsen, W.: Elemente der exakten Erblichkeitslehre. Jena: Gustav Fischer 1909
Koltes, J. E., Cole, J. B., Clemmens, R., Dilger, R. N., Kramer, L. M., Lunney, J. K., McCue, M. E., McKay, S. D., Mateescu, R. G., Murdoch, B. M., Reuter, R., Rexroad, C. E., Rosa, G. J. M., Serão, N. V. L., White, S. N., Woodward-Greene, M. J., Worku, M., Zhang, H., and Reecy, J. M.: A Vision for Development and Utilization of High-Throughput Phenotyping and Big Data Analytics in Livestock. Frontiers in Genetics 10 (2019). doi:10.3389/fgene.2019.01197
Lehner, B.: Genotype to phenotype: lessons from model organisms for human genetics. Nature Reviews Genetics 14/3, 168–178 (2013). doi:10.1038/nrg3404
Liu, C. Y., Maity, A., Lin, X. H., Wright, R. O., and Christiani, D. C.: Design and analysis issues in gene and environment studies. Environmental Health 11 (2012). https://doi.org/10.1186/1476-069X-11-93
Long, A., Liti, G., Luptak, A., and Tenaillon, O.: Elucidating the molecular architecture of adaptation via evolve and resequence experiments. Nature Reviews Genetics 16, 567–582 (2015). doi:10.1038/nrg3937
Maney, D. L.: Perils and pitfalls of reporting sex differences. Philosophical Transactions of the Royal Society B-Biological Sciences 371/1688 (2016). doi:10.1098/rstb.2015.0119
Manolio, T., Collins, F., Cox, N. J., Goldstein, D. B., Hindorff, L. A., Hunter, D. J., McCarthy, M. I., Ramos, E. M., Cardon, L. R., Chakravarti, A., Cho, J. H., Guttmacher, A. E., Kong, A., Kruglyak, L., Mardis, E., Rotimi, C. N., Slatkin, M., Valle, D., Whittemore, A. S., Boehnke, M., Clark, A. G., Eichler, E. E., Gibson, G., Haines, J. L., Mackay, T. F. C., McCarroll, S. A., and Visscher, P. M.: Finding the missing heritability of complex diseases. Nature 461/7265, 747–753 (2009). doi:10.1038/nature08494
Mendel, G.: Versuche über Pflanzen-Hybriden. Verhandlungen des naturforschenden Vereines in Brünn, IV, 3–47 (1866)
Meuwissen, T., Hayes, B., and Goddard, M.: Genomic selection: A paradigm shift in animal breeding. Animal Frontiers 6/1, 6–14 (2016). https://doi.org/10.2527/af.2016-0002
Meuwissen, T. H. E., Hayes, B. J., and Goddard, M. E.: Prediction of total genetic value using genome-wide dense marker maps. Genetics 157/4, 1819–1829 (2001)
Narasimhan, V. M., Hunt, K. A., Mason, D., Baker, C. L., Karczewski, K. J., Barnes, M. E. R., Barnett, A. H., Bates, C., Bellary, S., Bockett, N. A., Giorda, K., Griffiths, C. J., Hemingway, H., Jia, Z., Kelly, M. A., Khawaja, H. A., Lek, M., McCarthy, S., McEachan, R., O'Donnell-Luria, A., Paigen, K., Parisinos, C. A., Sheridan, E., Southgate, L., Tee, L., Thomas, M., Xue, Y., Schnall-Levin, M., Petkov, P. M., Tyler-Smith, C., Maher, E. R., Trembath, R. C., MacArthur, D. G., Wright, J., Durbin, R., and van Heel, D. A.: Health and population effects of rare gene knockouts in adult humans with related parents. Science 352/6284, 474–477 (2016). doi:10.1126/science.aac8624
Nasmyth, K.: The magic and meaning of Mendel's miracle. Nature Reviews Genetics 23/7, 447–452 (2022). doi:10.1038/s41576-022-00497-2
Nolan, P. M., Peters, J., Strivens, M., Rogers, D., Hagan, J., Spurr, N., Gray, I. C., Vizor, L., Brooker, D., Whitehill, E., Washbourne, R., Hough, T., Greenaway, S., Hewitt, M., Liu, X., McCormack, S., Pickford, K., Selley, R., Wells, C., Tymowska-Lalanne, Z., Roby, P., Glenister, P., Thornton, C., Thaung, C., Stevenson, J. A., Arkell, R., Mburu, P., Hardisty, R., Kiernan, A., Erven, A., Steel, K. P., Voegeling, S., Guenet, J. L., Nickols, C., Sadri, R., Nasse, M., Isaacs, A., Davies, K., Browne, M., Fisher, E. M., Martin, J., Rastan, S., Brown, S. D., and Hunter, J.: A systematic, genome-wide, phenotype-driven mutagenesis programme for gene function studies in the mouse. Nature Genetics 25/4, 440–443 (2000)
Nuesslein-Volhard, C., and Wieschaus, E.: Mutations affecting segment number and polarity in Drosophila. Nature 287/5785, 795–801 (1980) doi:10.1038/287795a0
Pallares, L. F.: Searching for solutions to the missing heritability problem. eLife 8. (2019) doi:10.7554/eLife.53018
Pallares, L. F., Lea, A. J., Han, C. R., Filippova, E. V., Andolfatto, P., and Ayroles, J. F.: Dietary stress remodels the genetic architecture of lifespan variation in outbred Drosophila. Nature Genetics 55/1, 123–129 (2023) doi:10.1038/s41588-022-01246-1
Rancati, G., Moffat, J., Typas, A., and Pavelka, N.: Emerging and evolving concepts in gene essentiality. Nature Reviews Genetics 19/1, 34–49 (2018). doi:10.1038/nrg.2017.74
Randerson, J. P., and Hurst, L. D.: The uncertain evolution of the sexes. Trends in Ecology and Evolution 16/10, 571–579 (2001) doi:10.1016/s0169-5347(01)02270-4
Rask-Andersen, M., Karlsson, T., Ek, W. E., and Johansson, A.: Modification of Heritability for Educational Attainment and Fluid Intelligence by Socioeconomic Deprivation in the UK Biobank. American Journal of Psychiatry 178/7, 625–634 (2021). doi:10.1176/appi.ajp.2020.20040462
Reis, H. T., and Carothers, B. J.: Black and white or shades of gray: Are gender differences categorical or dimensional? Current Directions in Psychological Science 23, 19–26 (2014). doi:10.1177/0963721413504105
Richard, M. and Yvert, G.: How does evolution tune biological noise? Frontiers in Genetics 5 (2014). doi:10.3389/fgene.2014.00374
Rockman, M. V.: The QTN program and the alleles that matter for evolution: all that's gold does not glitter. Evolution 66/1, 1–17 (2011). doi:10.1111/j.1558-5646.2011.01486.x
Silvers, W. K.: The Coat Colors of Mice. A Model for Mammalian Gene Action and Interaction. New York: Springer-Verlag 1979
Sittig, L. J., Carbonetto, P., Engel, K. A., Krauss, K. S., Barrios-Camacho, C. M., and Palmer, A. A.: Genetic background limits generalizability of genotype-phenotype relationships. Neuron 91/6, 1253–1259 (2016). doi:10.1016/j.neuron.2016.08.013
Sohail, M., Maier, R. M., Ganna, A., Bloemendal, A., Martin, A. R., Turchin, M. C., Chiang, C.WK, Hirschhorn, J., Daly, M. J., Patterson, N., Neale, B., Mathieson, I., Reich, D., and Sunyaev, S. R.: Polygenic adaptation on height is overestimated due to uncorrected stratification in genome-wide association studies. eLife 8 (2019). doi:10.7554/eLife.39702
Stanley, H.: Galton on Natural Inheritance. Nature 40, 642–643 (1889). doi:10.1038/040642c0
Thoday, J. M., and Thompson, J. N.: The number of segregating genes implied by continuous variation. Genetica 46, 335–344 (1976)
Visscher, P. M.: Human complex trait genetics in the 21st century. Genetics 202, 377–379 (2016). doi:10.1534/genetics.115.180513
Visscher, P. M., Brown, M. A., McCarthy, M. I., and Yang, J.: Five years of GWAS discovery. American Journal of Human Genetics 90, 7–24 (2012). doi:10.1016/j.ajhg.2011.11.029
Visscher, P. M., Hemani, G., Vinkhuyzen, A. A. E., Chen, G. B., Lee, S. H., Wray, N. R., Goddard, M. E., and Yang, J.: Statistical power to detect genetic (co)variance of complex traits using snp data in unrelated samples. Plos Genetics 10/4 (2014). https://doi.org/10.1371/journal.pgen.1004269
Waddington, C. H.: Genetic assimilation of an acquired character. Evolution 7/2, 118–126 (1953). https://doi.org/10.1111/j.1558-5646.1953.tb00070.x
Waddington, C. H.: The Strategy of Genes. London: Allen and Unwin (1957). https://doi.org/10.4324/9781315765471
Wagner, A.: Robustness and Evolvability in Living Systems. Princeton University Press (2007)
Weeden, N. F.: Are Mendel's Data Reliable? The Perspective of a Pea Geneticist. Journal of Heredity 107/7, 635–646 (2016) https://doi.org/10.1093/jhered/esw058
White, D., and Rabago-Smith, M.: Genotype-phenotype associations and human eye color. Journal of Human Genetics 56/1, 5–7 (2011). https://doi.org/10.1038/jhg.2010.126
Wellcome Trust Case Control Consortium: Genome-wide association study of 14,000 cases of seven common diseases and 3,000 shared controls. Nature 447/7145, 661–678 (2007). doi:10.1038/nature05911
Wood, A. R., Esko, T., Yang, J., et al.: Defining the role of common variation in the genomic and biological architecture of adult human height. Nature Genetics 46/11, 1173–1186 (2014). https://doi.org/10.1038/ng.3097
Wray, N. R., Wijmenga, C., Sullivan, P. F., Yang, J., and Visscher, P. M.: Common disease is more complex than implied by the Core Gene Omnigenic Model. Cell 173/7, 1573–1580 (2018). https://doi.org/10.1016/j.cell.2018.05.051
Yang, J, Manolio, T. A., Pasquale, L. R., Boerwinkle, E., Caporaso, N., Cunningham, J. M., de Andrade, M., Feenstra, B., Feingold, E., Hayes, M. G., Hill, W. G., Landi, M. T., Alonso, A., Lettre, G., Lin, P., Ling, H., Lowe, W., Mathias, R. A., Melbye, M., Pugh, E., Cornelis, M. C., Weir, B. S., Goddard, M. E., and Visscher, P. M.: Genome partitioning of genetic variation for complex traits using common SNPs. Nature Genetics43/6, 519–525 (2011). https://doi.org/10.1038/ng.823
Yang, J., Benyamin, B., McEvoy, B. P., Gordon, S., Henders, A. K., Nyholt, D. R., Madden, P. A., Heath, A. C., Martin, N. G., Montgomery, G. W., Goddard, M. E., and Visscher, P. M.: Common SNPs explain a large proportion of the heritability for human height. Nature Genetics 42/7, 565–569 (2010). https://doi.org/10.1038/ng.608
Zhang, W. Y., Reeves, G. R., and Tautz, D.: Testing Implications of the Omnigenic Model for the Genetic Analysis of Loci Identified through Genome-wide Association. Current Biology 31/5 (2021). https://doi.org/10.1016/j.cub.2020.12.023